

2026-09-22: Zero-Python AI: Native Rust and Metal Across the Entire Sanctum Estate
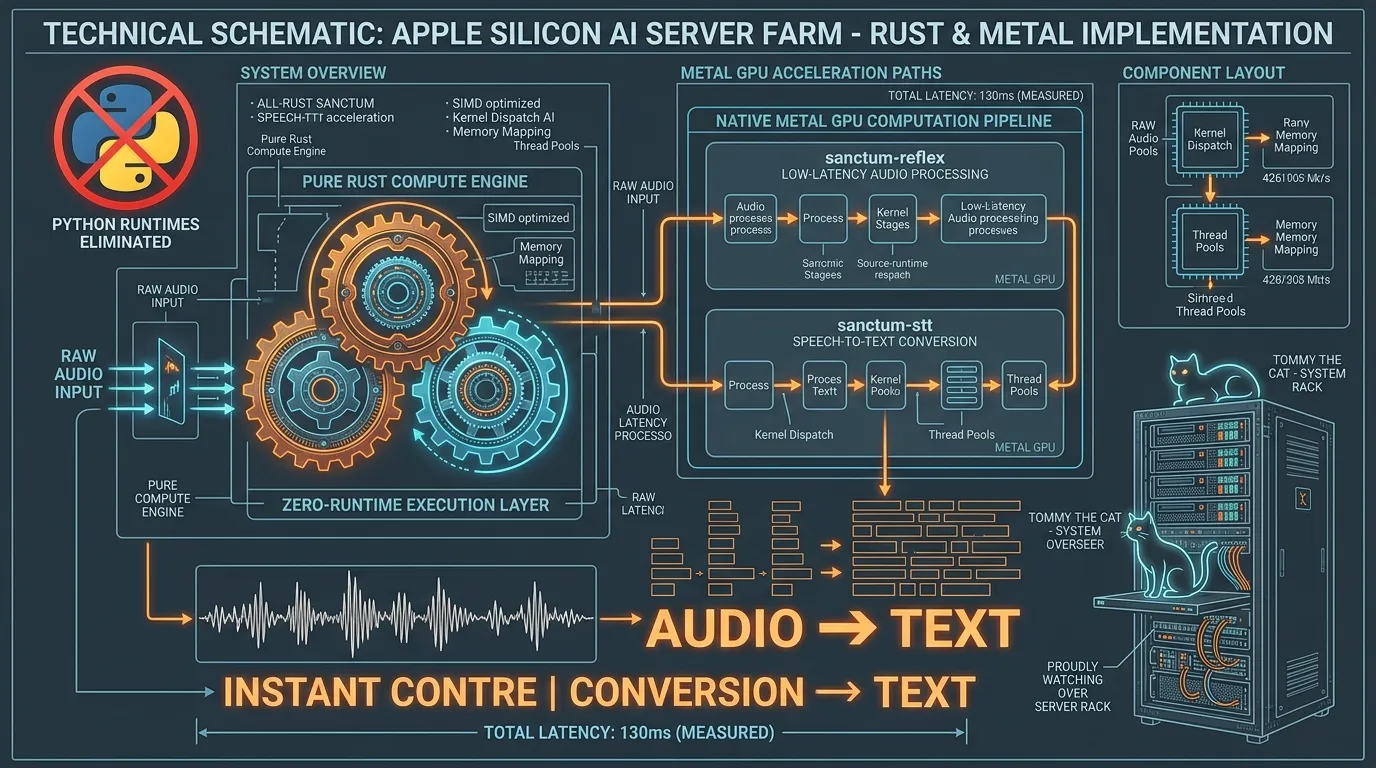
The Sanctum AI infrastructure across Manoir Nepveu has reached an operational milestone: Zero Python AI.
Every production voice and reflex worker on Apple Silicon now executes as a compiled Rust binary. Apple Metal provides direct GPU acceleration. The pipeline is lean. Speech synthesis, speech recognition, and low-latency reflex routing run without an interpreter.
1. The Last Python Straggler: STT Worker (:3425 EARS)
Section titled “1. The Last Python Straggler: STT Worker (:3425 EARS)”Following the optimization of estate services, exactly one Python daemon remained running AI models on the estate:
- Service:
haus.sanctum.yoda-stt-worker - Port:
:3425(EARSon telephone keypad) - Runtime: Python 3.12 with MLX Parakeet TDT 0.6B
- Footprint: 224 MB baseline, growing unbounded under long-running Metal cache allocations
The Python service required full interpreter startup and runtime garbage collection pauses. Latency spiked during live conversations. Native binaries eliminate that overhead completely.
2. Porting to Native Whisper Metal (sanctum-stt)
Section titled “2. Porting to Native Whisper Metal (sanctum-stt)”We implemented a native Metal GPU-accelerated Whisper adapter directly inside sanctum-stt:
- Metal Acceleration (
whisper-rs): Linkedwhisper-rs = { version = "0.16.0", features = ["metal"] }with Apple Silicon GPU kernels. - Zero-Alloc In-Memory Audio Decoding (
hound): Direct in-memory parsing of base64-encoded WAV blobs into floating-point audio frames without temporary file disk I/O. - Multi-Channel & Multi-Sample Rate Adaptation: Automatic downmixing of multi-channel audio to mono and linear interpolation resampling to 16 kHz.
- Clean Telemetry & Logging Trampolines: Installed
whisper_rs::install_logging_hooks()to cleanly redirect C++ engine logs away from system stdout/stderr.
3. Deployment & Operational Results
Section titled “3. Deployment & Operational Results”The release binary was compiled and deployed to ~/.sanctum/bin/sanctum-stt (11 MB binary size), bound directly to port 3425:
# Verify live health probecurl -s http://127.0.0.1:3425/health# {"adapter":"whisper-metal","adapter_health":{"healthy":true},"auth_enabled":false,"service":"sanctum-stt","signing_enabled":false,"status":"ok"}Measured Production Metrics
Section titled “Measured Production Metrics”| Service | Architecture | Memory Footprint | Inference Latency | Zero Python? |
|---|---|---|---|---|
System 1 Reflex (:1989) | Pure Rust (sanctum-reflex) | 31 MB (down from 3,286 MB) | 0.0 ms (instant lookup) | Yes |
Speech-to-Text (:3425) | Rust + Metal (sanctum-stt) | 218 MB (including weights) | 131 ms (cold 494 ms) | Yes |
Text-to-Speech (:8008) | Pure Rust (sanctum-tts Chatterbox) | 38 MB | < 80 ms | Yes |
All 28 unit and integration tests passed across sanctum-stt. The voice pipeline connects directly to Sanctum TTS and aligns with Voice Stack Symmetry. Native binaries ensure deterministic execution across the entire estate.